Home

Menu

Close
Prepare High-Integrity Data Sets to Build Trustworthy AI
Published:
September 11, 2026
Why preparing high-integrity data sets matters now
Imagine building a house with shaky foundations or a car with unreliable parts. It would not be safe or last long. In the world of Artificial Intelligence (AI) today, something similar is happening. Many AI systems are being built using "low-trust" data. This data is often scraped from the internet without much care, and it can be full of mistakes, unfair ideas, or even made-up information. This way of gathering information creates a big problem, a kind of "AI bottleneck," because good AI needs good data to learn from.
When AI relies on this kind of poor data, it creates serious risks for everyone. Big companies, government groups, and even non-profit organizations that use AI can face problems like biased decisions, wrong predictions, and a general loss of trust.
This bad data can lead to something called "Synthetic Drift," where the true meaning of information gets lost or changed as it moves through digital systems. For example, if an AI is trained on biased historical data, it might make unfair decisions about loan applications or job candidates in 2026. Experts agree that knowing where your data comes from and how it was collected is very important for AI to be fair and responsible [PDF] Data Governance Working Group A Framework Paper for GPAI's ....
That is why preparing high-integrity data sets is so important right now. It means gathering, cleaning, and labeling data in a very careful and ethical way. This ensures that the information AI learns from is true, fair, and reflects real human values. This guide will walk you through how to build these trustworthy data sets. We will look at practical steps, ethical rules, and smart ways to manage data. Our goal is to help you create AI systems that you and everyone else can truly trust.
Building good AI starts with having a strong moral compass for your data.
This means making sure the data sets AI learns from are not just correct, but also fair and respectful. In 2026, putting ethics at the heart of how we design and use data is super important for big companies, government groups, and non-profits alike.
Here are the main ethical ideas for creating good data sets:
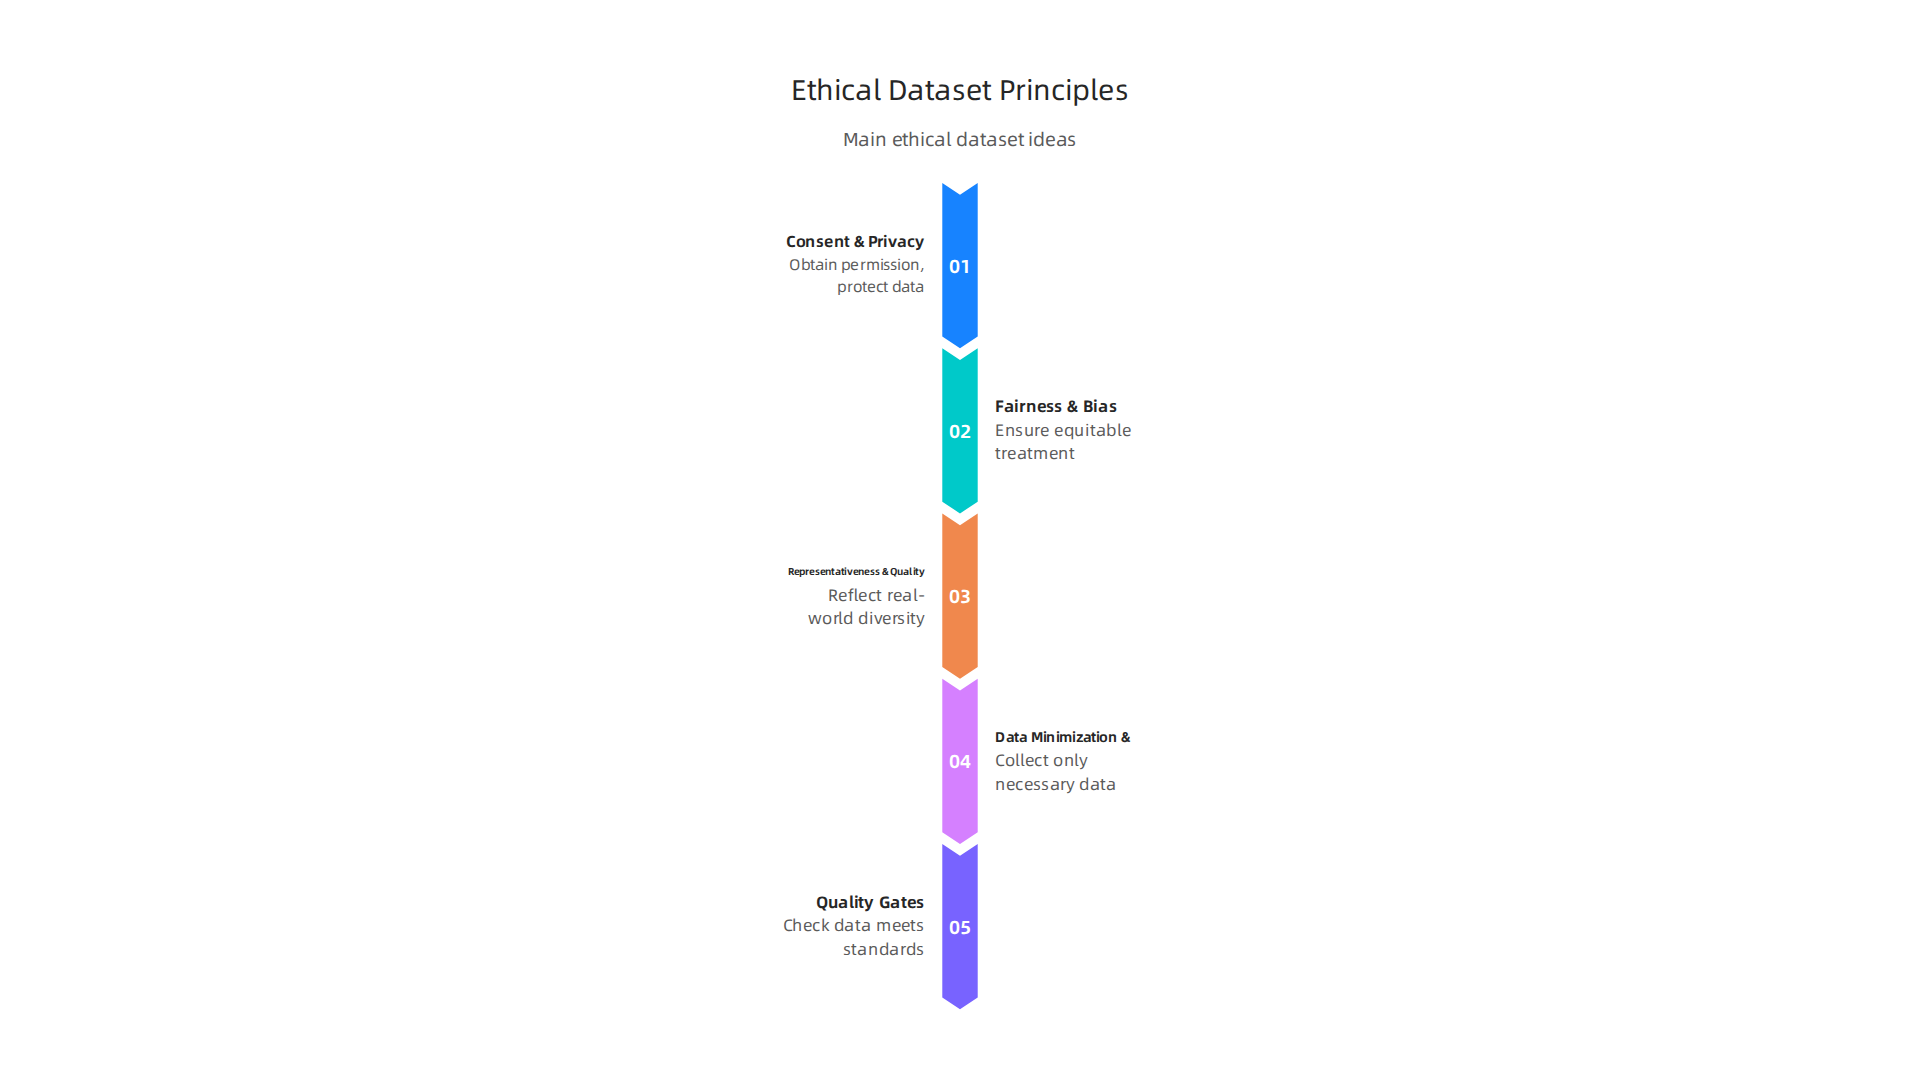
1. Consent and Privacy
This is about respecting people's information. It means:
- Getting Permission: Always ask people if you can use their data. This is true for personal information, health records, or anything private.
- Keeping it Safe: Protect data from being seen by the wrong people. Make sure it is stored securely.
- Being Clear: Tell people how their data will be used. Do not hide anything.
For organizations, this maps to clear rules for collecting and storing data. It also means making sure data is looked after throughout its life, from when it is first gathered to when it is no longer needed Understanding data governance in AI.
2. Fairness and Removing Bias
AI should treat everyone equally. To make sure of this:
- Check for Old Biases: Data can sometimes carry unfair ideas from the past. For example, if old loan data shows fewer loans given to certain groups, AI trained on this data might keep making those same unfair choices. We must actively work to find and fix these biases in our data sets.
- Represent Everyone: Make sure your data includes a wide range of people and situations. If your data only shows one type of person, the AI might not work well for others. This is about making sure your data is representative.
- Equal Outcomes: The goal is for AI to make fair decisions for everyone, regardless of their background.
The UK government's Data and AI Ethics Framework talks about fairness and ensuring documentation of data sources to prevent bias Data and AI Ethics Framework - GOV.UK.
3. Representativeness and Quality
Good data needs to truly show the real world it is trying to understand.
- Real-World Reflection: Your data sets should mirror the diversity of the world you are working in. If you are building an AI for healthcare, your data should come from many different types of patients.
- High Quality: The data needs to be accurate and consistent. Think of it like a puzzle. If some pieces are wrong or missing, you cannot complete the picture. This involves strong data annotation assessment and checks to make sure every piece of data is correct. For example, having multiple people label the same data and comparing their answers can help improve quality The Ultimate AI Data Labeling Industry Overview (2026).
4. Data Minimization and Purpose
Do not collect more data than you need, and always know why you are collecting it.
- Only What's Necessary: Gather only the data that is absolutely needed for your AI's purpose. More data is not always better, especially if it is personal.
- Clear Purpose: Every piece of data should have a clear reason for being collected. This helps prevent data from being misused later.
These principles become specific rules for your data. For instance, when you train AI or use it for business intelligence analytics software, you need clear standards for how complete the data is, how fresh it is, and if it truly represents different groups. By following these ideas, organizations can make sure their AI systems are built on a solid, ethical foundation, leading to more trustworthy results. If you want to dive deeper into how good data analysis can boost confidence in AI, consider learning how ethical data analysis builds trust in AI.
Now, let's talk about how to make sure these good data ideas actually happen. This is where data governance and following the law for sensitive data sets come in. It is like having a clear set of rules and a referee to make sure everyone plays fair with data.
Data Governance and Legal Compliance for Sensitive Datasets
For organizations big and small in 2026, it is super important to have clear plans for how to manage sensitive data. This helps keep things fair and legal.
1. Setting Up Your Data Rules
Think of this as building a team to watch over your data:
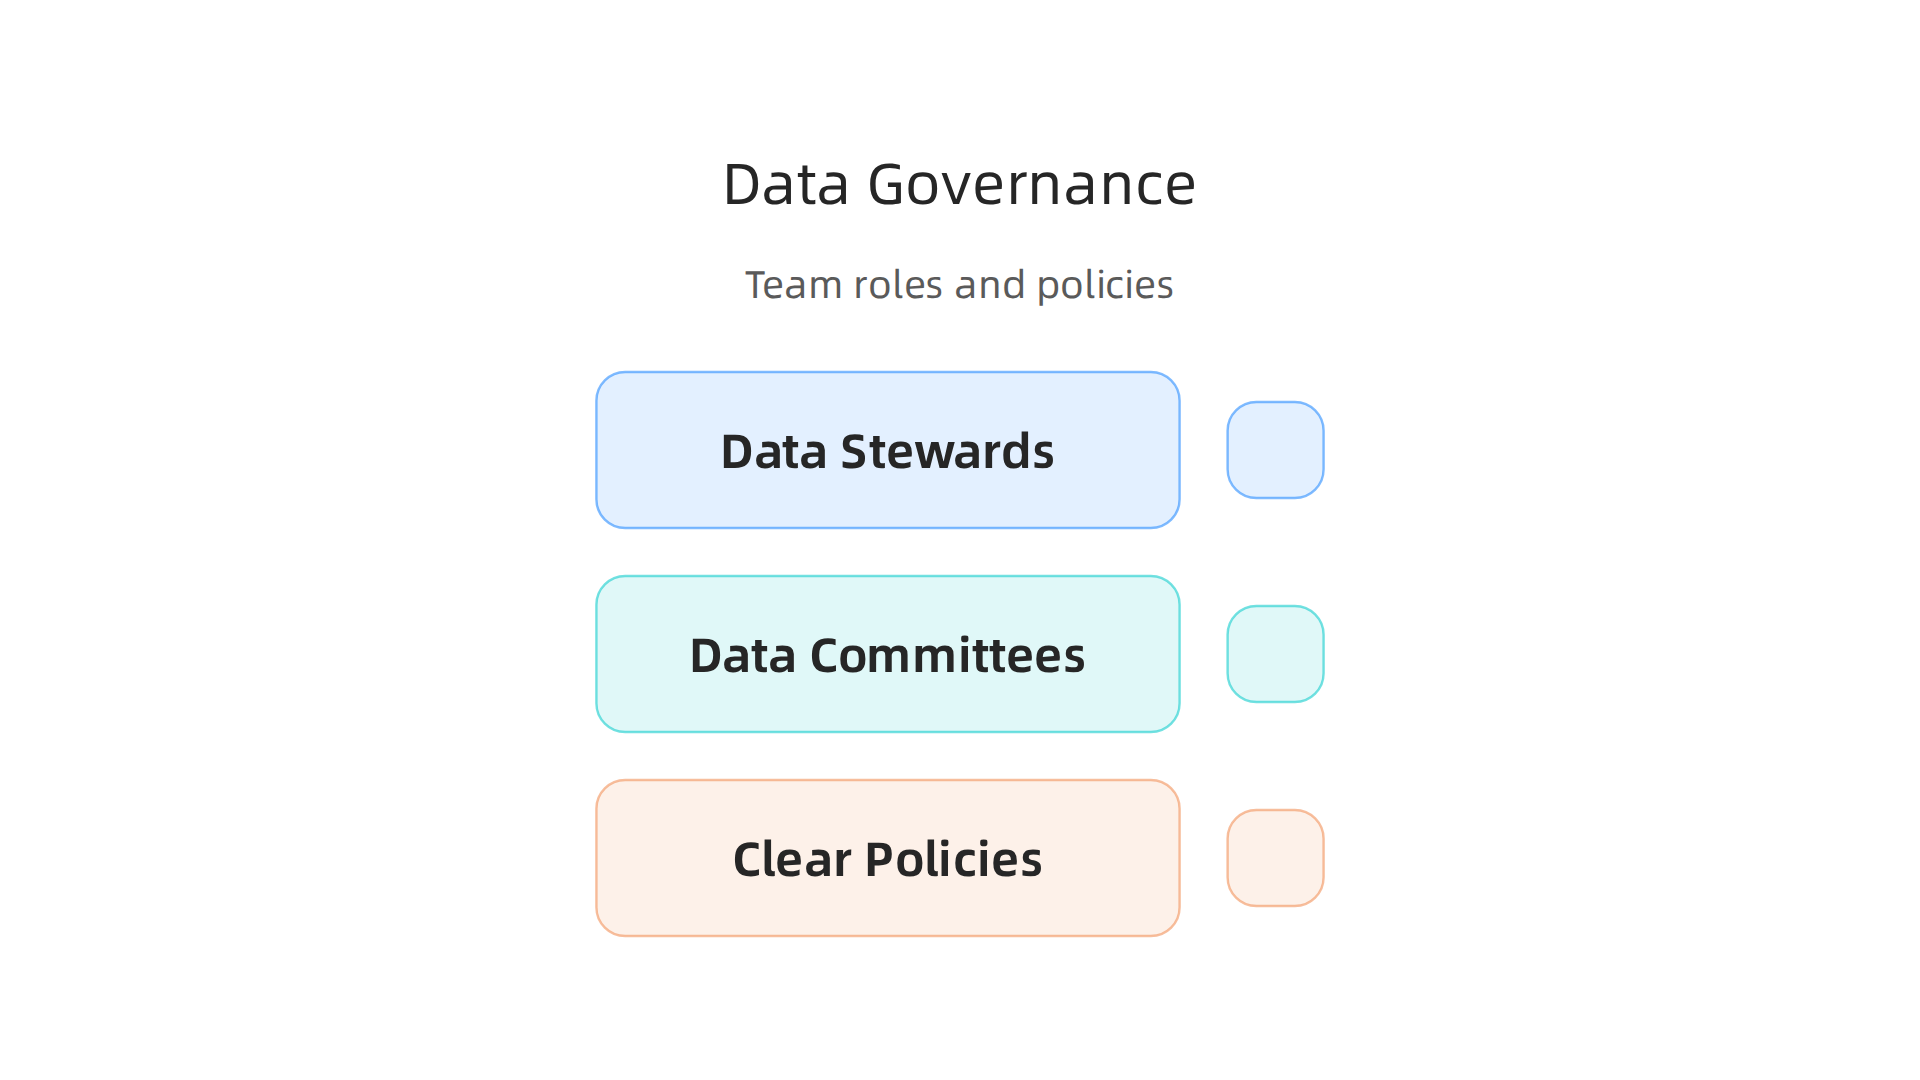
- Data Stewards: These are people who are in charge of specific data sets. They know what the data is, where it comes from, and who should be able to use it. They make sure the data stays clean and correct.
- Data Committees: This is a group of people from different parts of an organization. They meet to make big decisions about data rules. They decide on things like how long data should be kept and how to handle new kinds of data.
- Clear Policies: These are the written rules for everyone to follow. They spell out who can access certain data and for what reasons. For example, a policy might say that only certain employees can see health information, and only for specific patient care tasks. This also includes rules about where data comes from and how it changes over time, known as data provenance.
Having these structures helps make sure that the ethical ideas we talked about earlier, like consent and privacy, are actually put into practice. It makes sure that data sets are handled with care and respect. You can find more details on how to control who sees and uses AI data in a security classification guide master data protection and AI access.
2. Following the Law
Legal compliance means making sure all your data rules match the laws outside your organization.
There are many laws to think about:
- Privacy Laws: Laws like GDPR or CCPA tell us how to handle people's personal information. They say how data should be collected, stored, and used. For companies working with large amounts of information, especially what is big data, these laws are a big deal. New privacy techniques, like differential privacy, are being tested to protect sensitive information by adding "noise" to data so individual details can't be figured out, which is very helpful for privacy-preserving learning analytics using federated approaches Privacy-preserving learning analytics using federated.
- Rules for Specific Areas: Some types of data have extra rules. For example, healthcare data has very strict laws because it is so sensitive. Financial data also has its own set of rules.
- Buying and Selling Data: When government groups or big companies buy data sets or services that use data, they have to make sure the data was gathered ethically and legally. They need to check that the seller followed all the rules. This is crucial for business intelligence analytics software where data quality and ethical sourcing directly impact trust and reliability.
By setting up good governance and sticking to these laws, organizations can build AI systems that are both powerful and trustworthy. It helps everyone feel confident that their data is safe and used responsibly.
After ensuring you have strong rules and follow the law for your data, the next big step is deciding how to gather that data in the first place. Getting good data sets for AI means choosing smart ways to collect them. Let's look at the main ways to get data and what to think about for each.
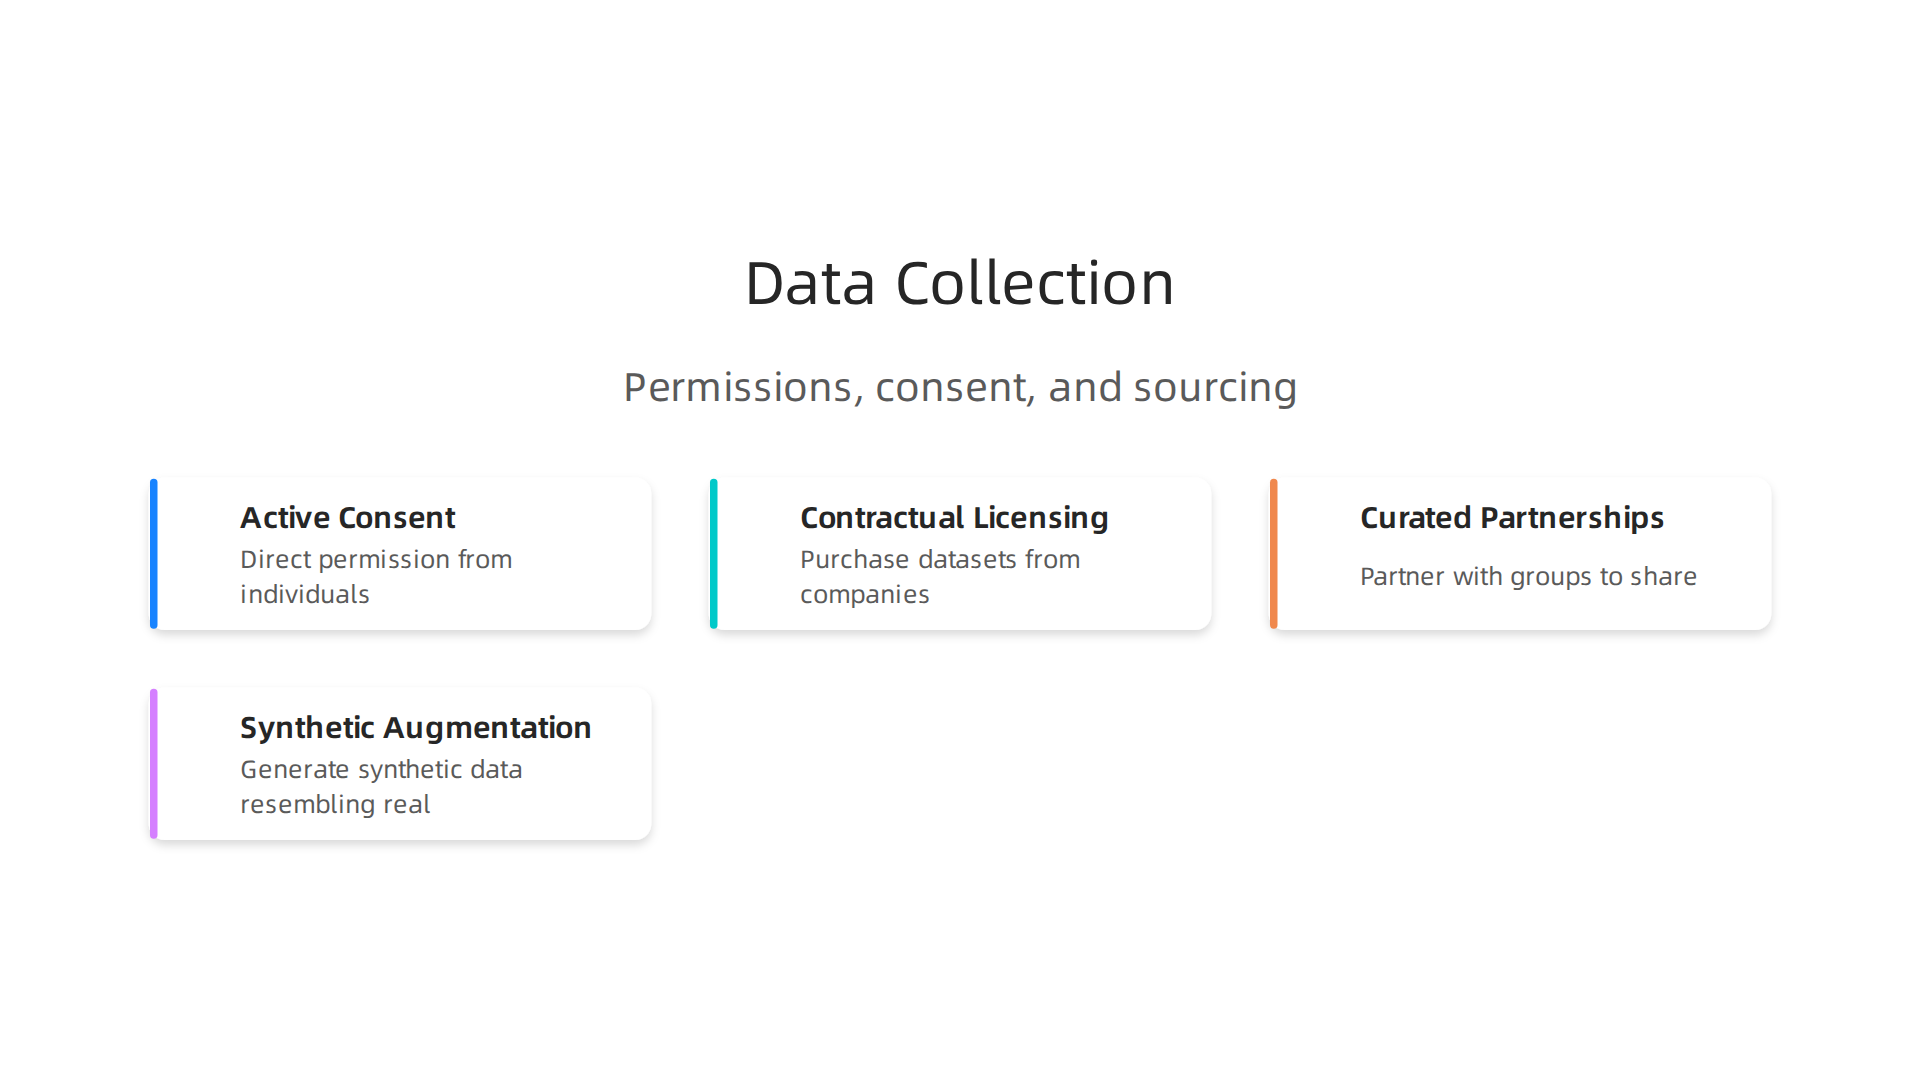
Data Collection Strategies: Permissions, Consent, and Sourcing
In 2026, building trustworthy AI starts with how you collect your data. There are different ways, and each has its own good points and things to watch out for.
1. Asking for Permission: Active Consent
This is when people directly say "yes" to their information being used. It is like asking a friend if you can borrow their toy. They understand what you will do with it and agree. This method is the best for ethical data use because it puts the person in charge of their own data. This kind of ethical data capture helps make sure AI models reflect real human values and are less likely to spread bad information.
2. Buying Data: Contractual Licensing
Sometimes, organizations buy data sets from other companies that specialize in collecting and selling data. These companies often deal with what is big data, meaning huge amounts of information. When you license data, you sign an agreement that says how you can use it. This can be quick, but you need to check carefully that the data was collected fairly and legally by the original source. Making sure the data comes from a trustworthy place is important for creating good AI.
3. Working Together: Curated Partnerships
This is when you team up with certain groups or businesses to share data. For example, a hospital might partner with a research center to share health data (after taking steps to protect privacy). These partnerships are built on trust and clear rules. They help you get very specific and high-quality data sets that might be hard to find otherwise. Such collaborations can also improve processes like data annotation assessment by ensuring experts review the data.
4. Making Fake Data: Synthetic Augmentation
Sometimes, you cannot get enough real data, or the real data is too private to use. This is where synthetic data comes in. It is like creating pretend data that looks and acts just like real data but doesn't come from actual people or events. This method can help fill gaps in your data sets and keep people's privacy safe. The use of synthetic data is a growing trend, as it can help reduce manual effort in data labeling and improve training models, as noted in the Data Annotation & Synthetic Data 2026: Tools & Trade-offs.
Choosing the Best Way to Get Your Data
When picking a data source, think about these things:
- Fidelity (How Real It Is): How closely does the data match the real world? Active consent usually gives the most real data.
- Ethics (Is It Fair?): Does the way you get the data respect people's rights and privacy?
- Cost (How Much Money): Some methods, like buying data, can be expensive.
- Risk (What Could Go Wrong?): What are the chances of problems like biased data or legal issues?
For your AI systems to be truly trustworthy, you need to make smart choices about where your data comes from. Having diverse and ethical sources is key for building solid trustworthy AI with ethical data and powering effective business intelligence analytics software. Looking into how organizations build "AI-ready" data can help with these decisions as well, by focusing on technical aspects and trustworthiness. A framework can help make government datasets ready for AI use by addressing these parts and ensuring ethical practices when collecting and preparing data for training AI models. This framework should also clearly state the source of the data for transparency purposes, as shown in the Guidelines and best practices for making government datasets ready fo….
After you have collected your data, the next big job is making sure that data is top-notch. Having good data sets isn't just about how you get them, but also how you prepare them. If your data is messy or wrong, your AI models might learn the wrong things. This can lead to what Dean Grey calls "Synthetic Drift," where AI outputs become less truthful over time. To avoid this, we need smart ways to clean, label, and check our data.
Data Quality: Cleaning, Labeling, and Annotation Workflows
Making sure your AI data is clean and properly organized is a huge step toward building trustworthy AI. Here are the best ways to prepare your data sets for AI training in 2026:
Making Data Clean and Tidy
- Removing Duplicates (Deduplication): Imagine having the same customer information listed five times. That's a mess! Deduplication means finding and taking out all the extra copies. This makes sure your AI doesn't get confused by repeated information and saves time and effort.
- Making Data Consistent (Normalization): Data comes from many places, so it might not all look the same. For example, "New York" might be written as "NY" or "N.Y." Normalization fixes this by making everything uniform. This helps your AI understand all the different entries as the same thing.
- Adding More Details (Enrichment): Sometimes, your data can be even more useful if you add extra information from other reliable sources. This process, called data enrichment, gives your AI a richer picture to learn from. For instance, if you have customer names, you might add their city from a public database.
Labeling and Annotation: Teaching AI What to See
Once your data is clean, the next step is to label it. Data labeling is like adding sticky notes to your data sets to tell the AI what each piece of information means. This is super important for AI to learn.
- Human Power and AI Help: In 2026, the best way to label data often combines both smart AI tools and real human experts. An AI might take a first guess at labeling data, which is called "pre-labeling." Then, human reviewers step in to check and fix any mistakes, especially for tricky cases. This "human-in-the-loop" process helps make the labels very accurate, as highlighted in the workflow for creating training data for AI models AI Data Labeling in 2026: How Training Data Is Made.
- Clear Instructions are Key: The people who label the data need very clear rules. These rules, or "annotation guidelines," show exactly how to tag different kinds of information. Good guidelines include examples of what to do and what not to do, making sure everyone labels data the same way. This helps make the resulting data sets consistent and useful, as suggested in expert guides for data annotation Data Labeling & Annotation: The Complete Expert Guide (2026).
Checking the Quality: Making Sure It's Right
Just labeling data isn't enough; you also need to check its quality. This is called quality assurance (QA).
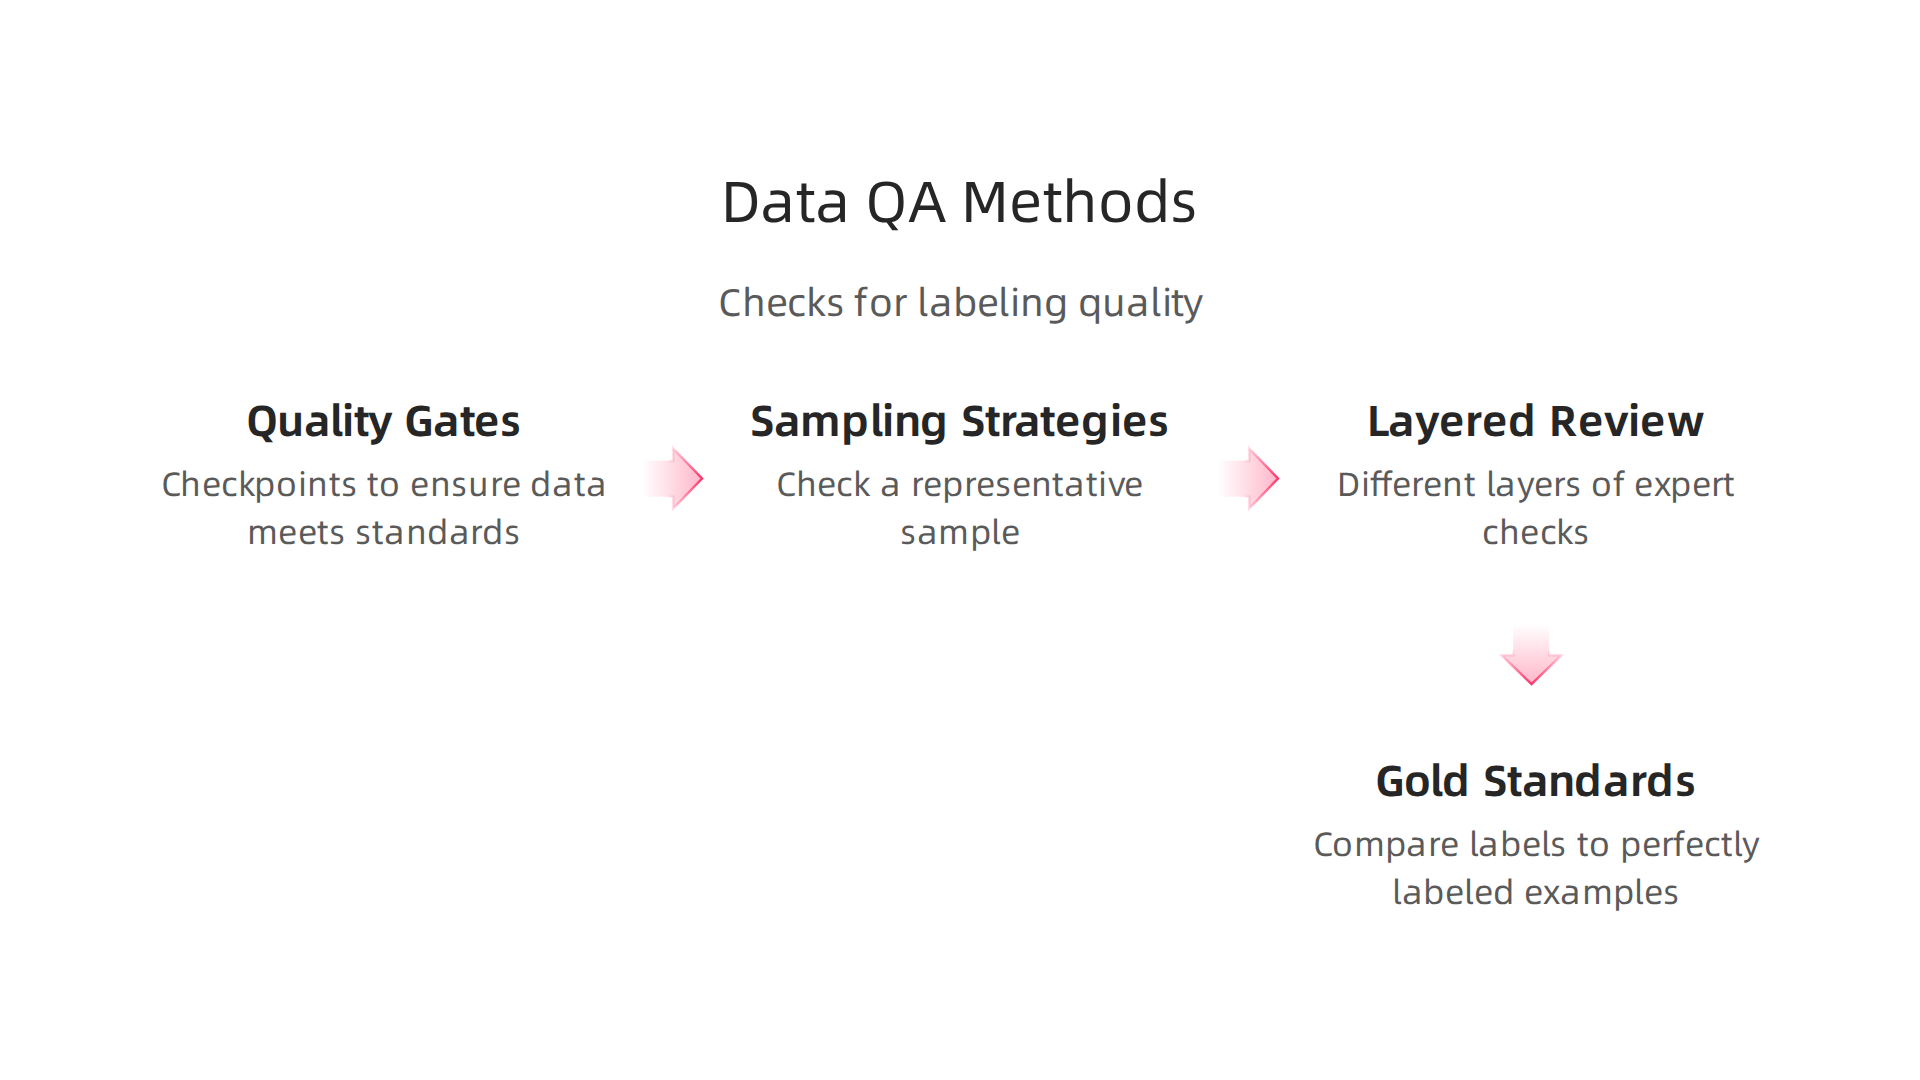
- Quality Gates: Think of these as checkpoints. At different stages of the data preparation, you set rules to make sure the data meets certain standards before moving on. If the data doesn't pass a "quality gate," it goes back for more work.
- Sampling Strategies: You can't check every single piece of data if you have what is big data. So, you check a small, but representative, sample of the data. This helps you understand the overall quality without checking everything. You need to continuously check to make sure the data stays good over time.
- Layered Review: Many experts recommend having different layers of checks. This might involve one person labeling, another person reviewing that work, and then a senior expert doing a final quality check. Automated tools can also help validate the data. This multi-layer approach helps catch errors and makes sure the data is very reliable, according to insights into the 2026 data annotation market The 2026 State of AI Data Annotation: Market - SyncSoft.AI.
- Gold Standards: To truly know if your labels are good, some companies use "gold standard" examples. These are pieces of data that have been perfectly labeled by experts. By comparing new labels to these gold standards, you can measure how accurate your team is. In 2026, building high-performing AI really comes down to having these gold standards and guidelines that are reviewed by experts 2026 Data Labeling Guide for Enterprises: Build High ....
By carefully cleaning, labeling, and checking your data sets, you are building a strong foundation for your AI. This focus on data quality is essential to unlock trustworthy AI systems with AI-ready data and is a critical part of mastering data annotation to build trustworthy AI. Without these steps, even the smartest AI models won't be able to give you reliable results.
By carefully cleaning, labeling, and checking your data sets, you are building a strong foundation for your AI. This focus on data quality is essential to unlock trustworthy AI systems with AI-ready data and is a critical part of mastering data annotation to build trustworthy AI. Without these steps, even the smartest AI models won't be able to give you reliable results.
Preventing Synthetic Drift and Managing Provenance
Even with carefully cleaned and labeled data, there's another challenge to keep an eye on: Synthetic Drift. This is a big problem Dean Grey talks about. It happens when the real world changes, but the AI's training data does not keep up. Or, worse, when the data itself gets distorted over time as it moves through different digital systems. When this happens, your AI models start learning from "old" or "wrong" information. This makes the AI's outputs less truthful over time and can mess up how it predicts human behavior.
For example, if your AI is trained on customer preferences from 2024, but it's now 2026 and tastes have changed a lot, the AI will make bad suggestions. This drift can cause AI to make poor decisions, spread misinformation, and lose the trust of users. To make sure your AI stays useful and trustworthy, you need to actively prevent this drift.
Tracking Data's Story: Provenance and Chain of Custody
This is where "provenance" comes in. Provenance is like keeping a detailed history book for all your data. It answers important questions: Where did this data come from? Who touched it? What changes were made to it, and when? Think of it as a recorded history of how data was produced and moved. For big companies dealing with what is big data, managing this can be tricky, but it's crucial.
To detect and stop Synthetic Drift, you need a clear "chain of custody" for your data sets. This means having records that cover every step data takes, from when it's first collected to when it's used to train AI. In 2026, companies are focusing on this to build trust.
Here's what a good chain of custody involves:
- Original Source: Knowing exactly where each piece of data came from, including the original organization, the date it was collected, and how it was gathered. Every data set needs this documented provenance.
- Changes Over Time: Keeping track of every tiny change. This includes who changed it, why, and what tools were used. It means logging things like hardware settings when data was captured, the exact way sensors were set up, and how your data annotation assessment rules have changed over time. This helps create auditable lineage.
- Versions and Updates: Saving different versions of your data sets as they evolve. This way, if a problem appears, you can look back at past versions to find out where things went wrong.
- Security and Access: Knowing who has accessed the data and when, to make sure it hasn't been tampered with. This is a key part of data provenance as an AI security control.
By keeping such detailed records, you can quickly spot when your data starts to drift away from reality. This allows you to update or fix your data sets and retrain your AI models with fresh, accurate information, actively fighting against Synthetic Drift and ensuring your AI remains trustworthy. This kind of diligent data management is essential for any modern business intelligence analytics software that relies on AI.
To truly build trust in AI, just knowing where your data comes from isn't enough. You also need to keep that data private and safe, especially when working with sensitive information. This means using smart techniques and controls that protect individual privacy while still letting your AI learn.
Technical Ways to Protect Privacy
In 2026, companies are using several advanced methods to make sure data stays private.
- Differential Privacy (DP): Imagine you have a large collection of data sets, but you don't want anyone to find out details about any single person in those sets. Differential privacy helps by adding a little bit of "noise" or randomness to the data before the AI sees it. This noise is carefully added so that the overall patterns in the data remain clear, but it's impossible to tell if any one person's information was part of the original data. This gives strong math-backed guarantees for privacy, keeping individual data points safe from being guessed or traced back to someone specific, as studies have shown when evaluating these mechanisms on various data sets. It protects against attacks that try to figure out personal details from AI model outputs Evaluation of Differential Privacy Mechanisms on ....
- Federated Learning (FL): This is a clever way for AI models to learn without ever seeing your actual private data. Instead of sending all your personal data to a central server, the AI model itself comes to your device (like your phone or computer). It learns from your data right there, on your device, and then only sends back a summary of what it learned. This summary doesn't contain any of your private information. Many studies focus on how federated learning, often combined with differential privacy, can help balance privacy and how well the AI works, especially for things like customer service and healthcare data Evaluation of Differential Privacy and Federated Learning .... For example, it's being used for teacher data privacy protection and even in digital language education Federated learning for teacher data privacy protection - PMC and PERFED: Privacy Preserving Personalized Federated Learning with Reinforcement and Meta-Learning for Digital Language Education.
- Secure Enclaves: These are like locked, super-safe boxes inside a computer's processor. You can put sensitive data and special programs inside these enclaves. Even if someone gains control of the rest of the computer, they can't peek inside the enclave or tamper with the data being processed there. This provides a high level of security for critical data analysis.
These methods are really important for handling what is big data ethically.
Everyday Security Controls
Beyond these technical tricks, basic security steps are still super important:
- Access Logging: Keep a detailed record of who accesses which data sets, when, and for how long. This helps you know if someone is looking at data they shouldn't be.
- Encryption: This means scrambling your data so only people with the right "key" can read it. You should encrypt data when it's stored and when it's moving from one place to another. This protects information even if someone manages to steal the data. You can learn more about how security tools protect your information in the cloud by reading about cloud security tools secure AI data and build trust in 2026.
Choosing the Right Approach for Your Needs
Not every privacy tool is right for every situation. You need to think about how mature each technique is and how it fits your company's "risk profile."
- Understand the Risk: Some data sets, like health records or financial details, are very sensitive and need the strongest protections. Other data might be less sensitive.
- Evaluate Maturity: Some techniques are newer than others. In 2026, federated learning and differential privacy are well-tested, with researchers constantly improving how they balance privacy with AI performance Balancing privacy and performance in federated learning. Make sure the tools you choose are reliable and have been proven to work.
- Consider Your Stakeholders: Think about everyone who cares about the data: customers, employees, legal teams, and business leaders. What are their worries? What level of privacy do they expect? Your choices should match these expectations.
By carefully picking and using these privacy-preserving techniques and security controls, you can make sure your AI systems are not only smart and useful but also truly trustworthy. This commitment to data ethics is key for any organization building AI, including those focusing on business intelligence analytics software.
After securing your valuable information, the next big step is to make sure your data sets are actually put to good use. This means setting up clear ways for your information to move from where it's kept safe to where it can help your business make smart decisions and power your AI. This process is called "operationalizing datasets."
Operationalizing Datasets for Business Intelligence and AI Production
To truly make the most of your data, you need to build strong connections between how you manage your data and how you use it for things like building AI models, checking how well those models are doing, and creating reports for your business insights. Think of these as pipelines that carry the data.
Designing these pipelines means creating a smooth path for your data. First, you need good "data stewardship." This is like having a manager for your data sets who makes sure they are clean, correct, and ready to use. This person also sets up rules for who can access the data and how long it's kept, especially for what is big data. In 2026, companies often assign specific people, called data stewards and owners, to oversee important data, ensuring quality and proper use Data Stewardship in 2026: 5-Part Framework + Roles Guide.
These pipelines then carry this well-managed data to different places. One place is for "model development," where AI teams use the data to teach new AI systems. Another stop is for "experiment tracking," which helps keep an eye on how different AI models are learning and performing. And finally, the data flows into "BI reporting," which creates easy-to-understand summaries for your business intelligence analytics software, helping leaders see important trends. Using trusted data services helps build strong pipelines that lead to trustworthy AI systems. You can learn more about how to build trustworthy AI with robust data pipelines.
It's also important to measure how well your data is doing. This means setting up goals and ways to check the "health" of your data sets. These are called metrics and Key Performance Indicators (KPIs). For example, you might track how often data is updated or how many errors it has. These measures should match what your company wants to achieve and how it wants to help people. By paying close attention to these metrics, businesses can make sure their data efforts are truly making a difference. Many companies have found success by improving their data quality, sometimes by as much as 80%, through better data governance and monitoring Establishing Enterprise Data Governance at a Global Scale | HCLTech. This kind of careful work ensures that your AI models and business insights are built on a strong, reliable foundation.
Summary
This article explains why high-integrity datasets are the foundation of trustworthy AI and shows how to build them in practice. It covers core ethics—consent, privacy, fairness—and explains how representativeness and quality prevent biased or misleading AI outcomes. The guide walks through governance and legal compliance, roles like data stewards, and practical collection strategies ranging from active consent to synthetic augmentation. You'll learn concrete steps for cleaning, annotating, and validating data with layered QA, gold standards, and sampling. The piece also describes how to stop Synthetic Drift through provenance, versioning, and chain-of-custody records, and it reviews privacy-preserving techniques such as differential privacy, federated learning, and secure enclaves. Finally, it explains how to operationalize datasets into pipelines for model development and business intelligence, and how to measure dataset health with KPIs so your AI stays accurate and trustworthy over time.